

Monitoring, Alerting & Optimization
Catch issues before your customers do.
24/7 visibility into every workflow, integration, and AI agent, with proactive alerts, root-cause investigation, and ongoing tuning to keep performance, reliability, and cost in check.
24/7
automated monitoring
<5min
average alert-to-action
30+
metrics tracked per workflow
100%
execution audit trail
24/7
automated monitoring
<5min
average alert-to-action
30+
metrics tracked per workflow
100%
execution audit trail
OPERATIONAL CONTROL
Always watching, always tuning
We provide active operational oversight to keep your workflows, AI agents, and integrations performing at peak efficiency. From real-time telemetry to zero-downtime maintenance, we continuously monitor, analyze, and optimize your entire backend ecosystem.
Real-Time Monitoring
Live status of every workflow, AI agent, and integration viewable in one unified dashboard. We deploy high-frequency telemetry monitors and instant interface state updates to display live enterprise health metrics.
Proactive Alerts
Get notified by email, SMS, or Slack the moment something fails, slows down, or drifts off baseline. We engineer automated diagnostic event triggers and immediate notification loops to inform your technical team.
Failure Investigation
Root-cause analysis when workflows misbehave, with full execution traces and input/output capture. We index comprehensive error logs and historical database states to accelerate post-incident debugging.
Performance Analytics
Throughput, latency, and success-rate trends over time so you spot regressions early. We compile deep operational transaction data into clean visual charts to optimize broad system infrastructure speeds.
Continuous Optimization
Ongoing tuning of logic, models, and resource usage to lower cost and improve reliability. We execute recursive system load audits and algorithmic enhancements to maximize server processing efficiency.
Maintenance & Updates
Keep integrations current as APIs, platforms, and AI models evolve without breaking what works. We monitor external endpoint deprecation schedules and patch operational codebases with zero downtime.
MEET SENTRY
The watch tower over every automation you run.
Sentry is our active surveillance and health-monitoring framework. Designed to maintain total operational control over your backend, Sentry continuously tracks, scores, and traces every workflow, integration, and AI call, giving you instant anomaly detection and full context to resolve issues before they disrupt your business.
Full execution traces
Every step recorded with timestamps, inputs, outputs, and external API responses.
SLA scoring
Each workflow gets a health score against the targets you care about.
Anomaly detection
Baselines learned automatically, alerts fire on unusual patterns, not just hard failures.
ONE PANE OF GLASS
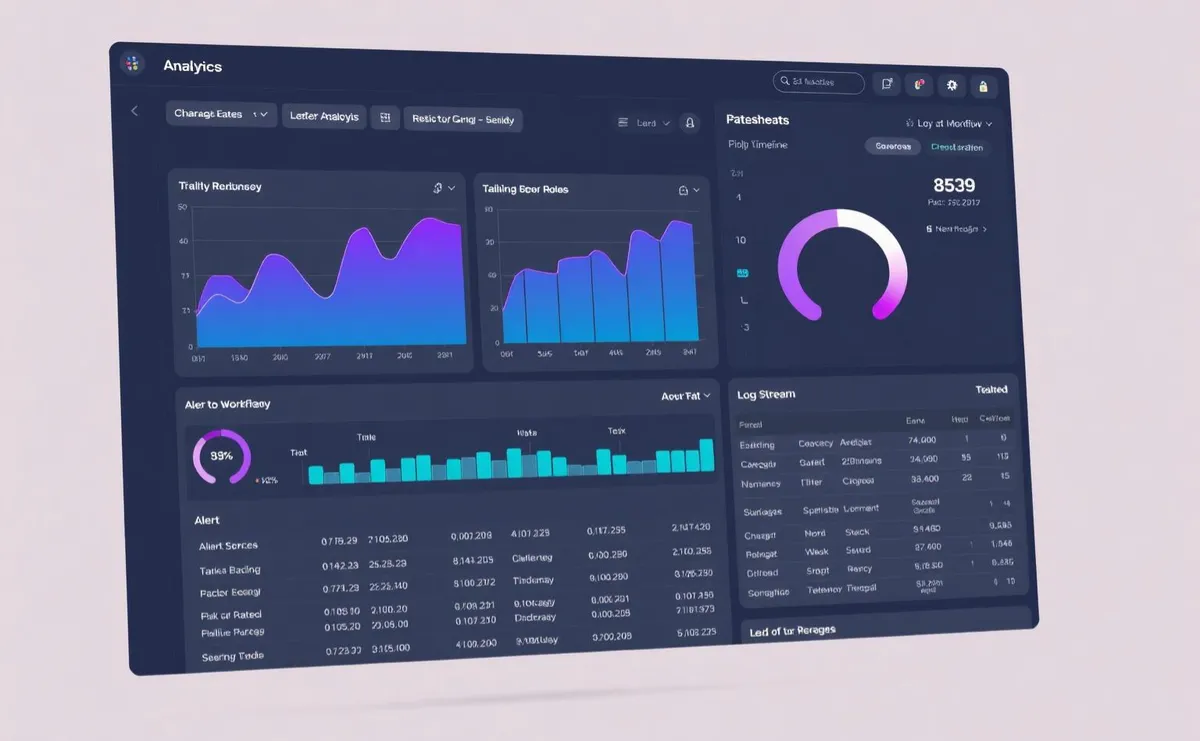
Every metric that matters
Stop stitching together logs, spreadsheets, and gut feel. Our monitoring dashboard surfaces the vital operational signals that predict performance issues, allowing your team to resolve bottlenecks instantly instead of searching through raw data.
Success & failure rates
Per workflow, per integration, per time window, with drill-down to the failing record.
Latency percentiles
p50, p95, p99 tracked over time so slowdowns surface before SLAs break.
Cost & token tracking
AI model usage and cloud spend mapped to the workflow that caused it.
Custom KPIs
Bring your own business metrics, leads created, invoices sent, tickets resolved.
OUR APPROACH
From signal to resolution
We use a proactive, data-driven strategy to monitor workflows, resolve root causes, and keep your systems reliable, secure, and optimized.
01
Instrument
Add tracing, metrics, and structured logs to every workflow and integration.
02
Baseline
Establish normal behavior, latency, volume, success rates, cost.
03
Alert
Wire up smart alerts to the right people on the right channel.
04
Investigate
When something breaks, we triage and fix root causes, not symptoms.
05
Optimize
Monthly tuning to cut latency, improve reliability, and lower cost.
Faster recovery
Cut mean-time-to-resolution by surfacing the failing step instantly.
Less rework
Auto-retries and dead-letter queues prevent dropped records.
Hours back per week
No more manual spot-checks of every integration and report.
Don't wait for things to break.
We watch your automations 24/7 and keep them running at peak performance,
so you can focus on the work that grows your business.
Related Services
Your trusted partner for comprehensive IT
solutions, cybersecurity, and business
technology services in the Greater
New Orleans area.
Covington, LA 70433


Mon-Fri: 8:00 AM - 6:00 PM
MANAGED SERVICES
DIGITAL PRESENCE
AI & AUTOMATION
COMPANY
Copyright 2026. Better Connected Technology Services. All Rights Reserved.

